Waymo Taxis Heading to Houston, Orlando, San Antonio
“The latest three testing stops on Waymo’s 2025 ‘road trip’ tour of the United States have been announced.
The self-driving company – which said in February that it wanted to test in at least 10 new cities across the United States this year – revealed three more destinations in a series of posts across social media.
On Instagram, it stated: ‘Learning and rolling, we’re excited to announce our next stops for testing and exploration: Houston, Orlando and San Antonio! These vibrant cities will provide unique and interesting learnings as we bring autonomous mobility to more communities. Get ready, the future is on the move!’
These cities join those already announced over the past few months.
At the start of February, Las Vegas and San Diego were named as the first ports of call.
Later that month New Orleans was also added to the schedule. By late March, Nashville was penciled in.
Earlier this month Dallas was announced too, alongside Boston – with the latter, in particular, sparking much interest and media attention at the prospect of a potential launch in a new part of the U.S., the northeast.”
“The human genome is made of about 3 billion base pairs of DNA — but much of it remains a mystery. Scientists understand the 2% of the human genome that codes for proteins relatively well, but have only limited knowledge of the remaining 98%. Our AlphaGenome model has already shown how single changes in these non-coding DNA regions can disrupt molecular processes like protein production, but the bigger picture remained unclear.
Today, we're introducing AlphaGenome Atlas, a database that predicts the effects of every possible single nucleotide variant in the human genome. We used the AlphaGenome AI model to pre-calculate the regulatory impact of all 9 billion single-letter genetic changes, resulting in a massive, 1-petabyte dataset. Our new Atlas helps scientists rapidly query this vast information.
To help researchers rapidly navigate this, the Atlas introduces the AlphaGenome Variant Impact (AVI) score. This single, easy-to-use score combines predictions for both coding and non-coding regions, allowing researchers to quickly prioritize the most promising avenues for research without sifting through thousands of data points.”
New $1 Million Prize Rewards Academic Truth-Telling
“Mr. Fryer raised the alarm about suppression of inconvenient findings in a November 2024 Wall Street Journal essay. He called for something like a MacArthur Fellowship or an X Prize for academic truth-telling. The prize should be large enough to matter, prestigious enough to serve as a public credential for scholars who were right when it was costly to be right. Shortly after that piece ran, we found each other and decided to launch the Carob Trust Prize for Academic Courage.
The prize awards $1 million each to as many as five social scientists a year who have demonstrated intellectual independence, published findings that were attacked rather than answered, and been validated by the evidence—despite the professional cost. The selection criteria are designed to distinguish courage from contrarianism: Nominees must show a sustained commitment to following logic and evidence regardless of pressure, a willingness to ask questions others avoid, and work that has shifted academic debate, public discourse or policy—often despite being misread, mischaracterized or vilified at the time of publication.
The inaugural prize is limited to the social sciences; in future years we hope to broaden it to additional disciplines and to add a category for institutional leadership. Nominations are open through Nov. 1, and the first winners will be announced in early 2027.”
Civilization has advanced by learning to preserve more knowledge with less matter.
J.K. Lundblad —
Summary: Human progress depends not only on discovering knowledge but also on preserving and transmitting it. From stone tablets to printed books and solid-state drives, storage media have become vastly lighter, denser, and faster. Over five thousand years, humanity has increased data density by trillions, making accumulated knowledge cheaper and more accessible than ever.
The astonishing conveniences and prosperity of modern civilization rest on two pillars: our mastery of energy and our relentless discovery of knowledge. Yet, discovering new knowledge alone was not enough for civilizational progress. To accumulate and build on discoveries across generations, humanity needed a way to encode knowledge onto a medium outside of our collective nervous system. From etching hieroglyphs into stone to digitally controlling electrons in modern solid-state drives (SSDs), humanity’s advancement in creating affordable, lightweight, and reliable data storage is astonishing.
Before the invention of written language, people usually transmitted knowledge orally. Fables and other knowledge had to be memorized and accurately recited to pass from one generation to the next. Transmitting knowledge this way, where data is stored only in the human mind, risks significant data loss. When Joe Huntergatherer, the only member of the tribe who had memorized the story of the Great Elder, was killed by an arrow, that story was forever lost. The fragility of oral transmission is why almost all human history, spanning hundreds of thousands of years, is lost to the erosive sands of time.
The invention of writing, the ability to etch, carve, or paint characters onto clay tablets, stone, and cave walls, allowed humans, for the first time, to store information outside the brain. The first clay inscriptions with readable script date from ~3,400 B.C. So long as another person was trained to interpret the inscribed hieroglyphs, characters, or letters, that knowledge was no longer subject to fallible human memory. However, stone inscriptions had relatively low information density.
To create a formula to measure the data density of storage media over time, I convert characters (letters and punctuation) into bits of information, then divide by the number of grams of matter needed to encode that information. A bit is a single binary digit, a zero or one, and roughly eight bits make up a single character. (View these calculations not as precise figures, but as order-of-magnitude approximations, since data density varies considerably from stone to book to drive.)
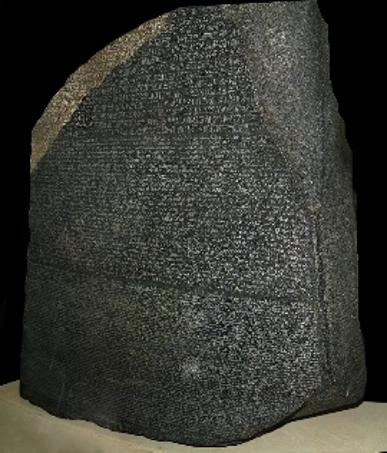
Let’s begin with stone engravings, using the famous Rosetta Stone as an example. The Rosetta Stone weighs roughly 750kg and contains the same text in three languages: Ancient Egyptian hieroglyphs on top, Egyptian Demotic script in the middle, and Ancient Greek on the bottom. To estimate the data density, I focused on the Greek portion of the stone, which accounts for roughly 1/3 of the stone’s total weight (about 250kg).
No source I could find provided a reliable count of the surviving Greek characters, so I calculated it twice independently. First, I compared a 19th-century publication’s line-by-line count with a high-resolution photo of the stone, which puts the original, undamaged text at about ~7,290 characters. Adjusting that figure for the approximately 20 percent of the stone that’s damaged or missing gives an estimated ~5,832 surviving characters. Second, I ran an AI optical character count directly off the damaged stone, which returned ~5,800. The two methods are close, so I use ~5,800 characters going forward.
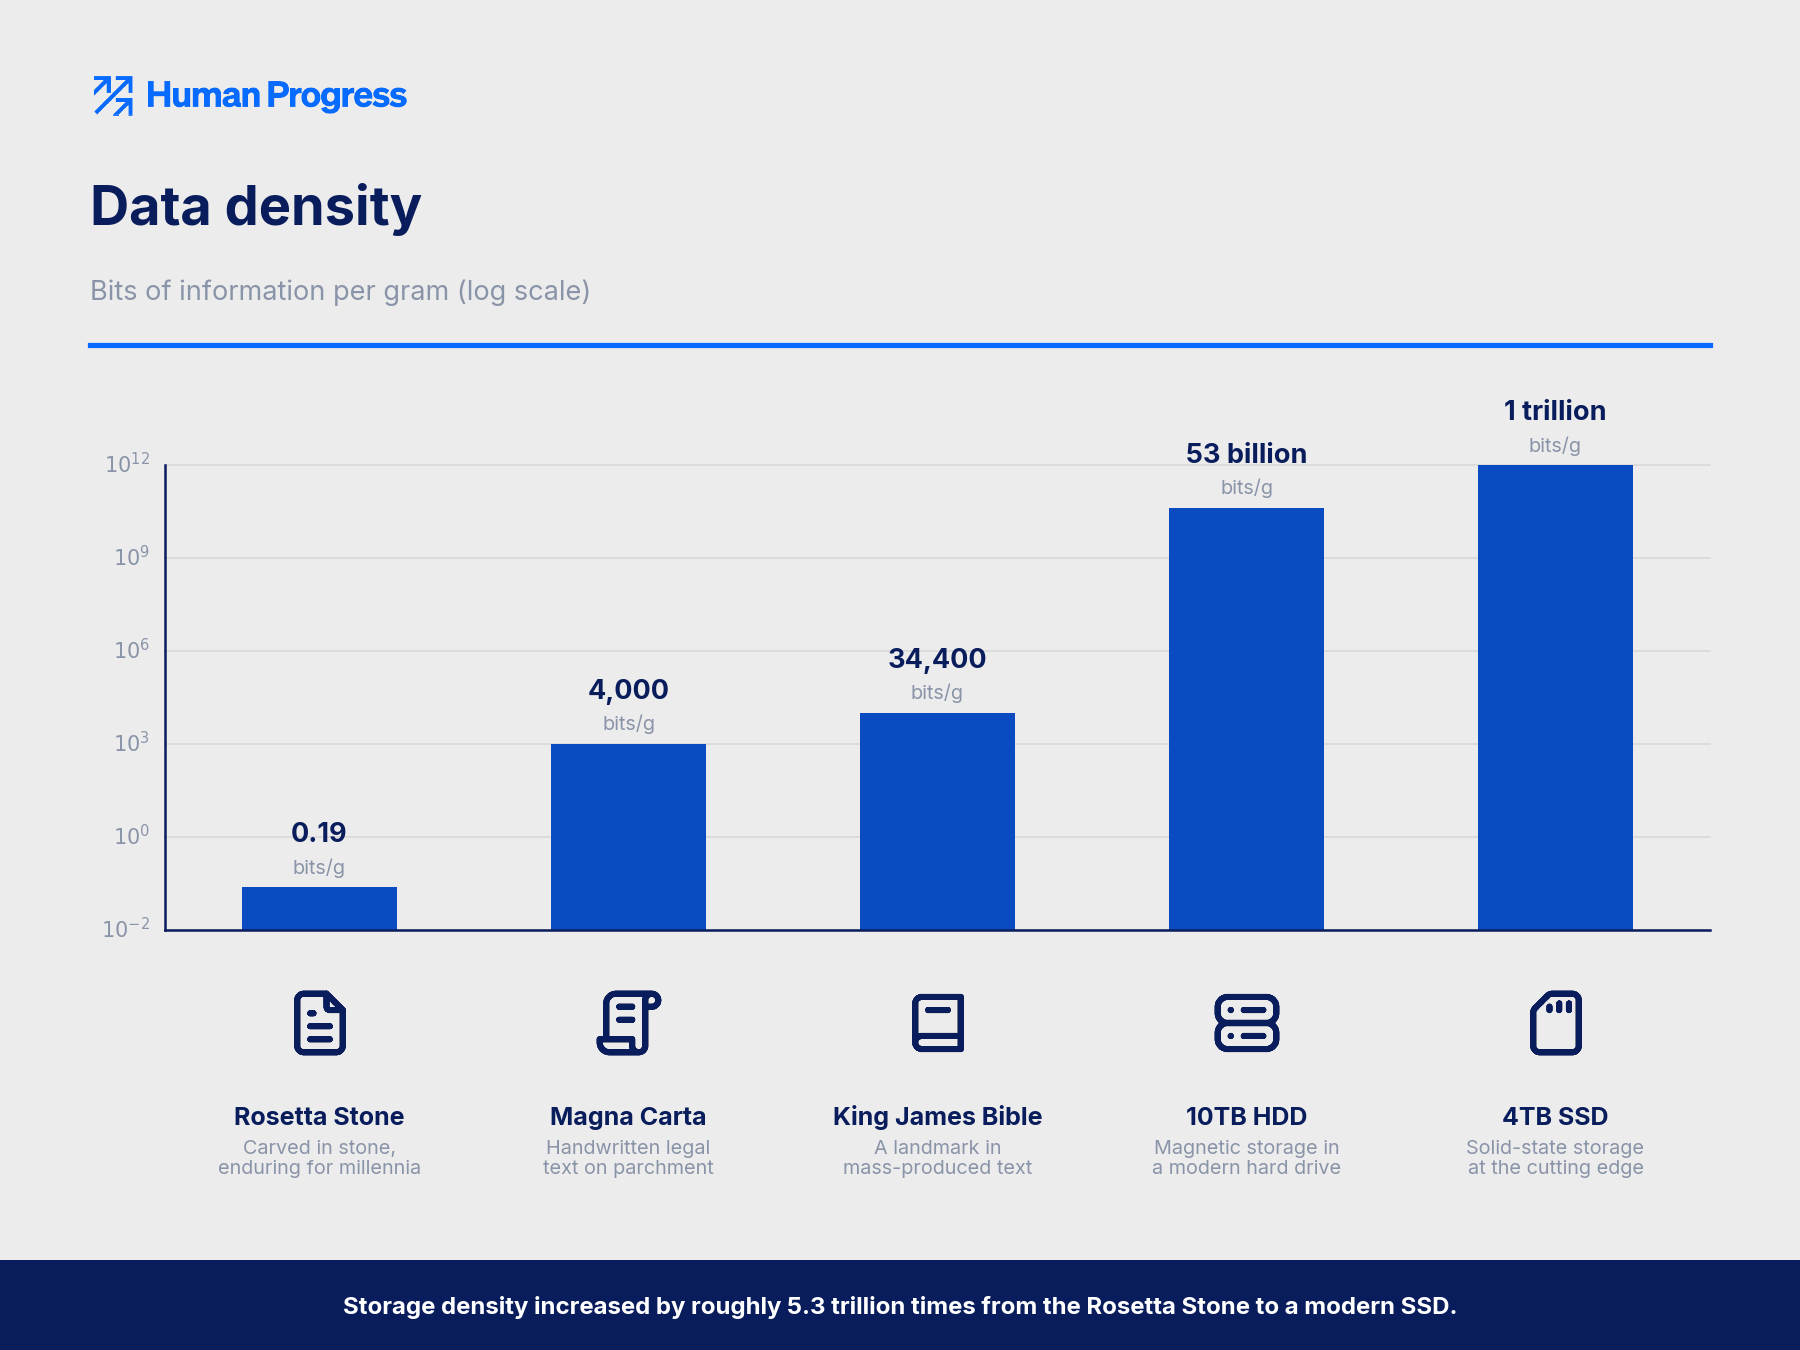
Since a single character of text equates to about 8 bits of information, the surviving 5,800 characters store 46,400 bits of data. Divided by the 250kg weight of the Greek portion, we arrive at a data density for the Rosetta Stone of ~0.19 bits/g.
With the discovery of agriculture and the rise of agrarian civilizations, the demands for knowledge storage and transmission media grew. The human population expanded, and a small but notable fraction began to congregate in small towns. As social and economic complexity grew, so did administration, trade, tax, and legal systems. Humans needed an easy way to perform and store the outputs of mathematical calculations, record taxes, and codify rules and regulations for personal and business conduct. Agrarian civilization, in short, demanded a storage medium with higher information density and faster read/write speeds (throughput). Enter papyrus, parchment, and paper.
Early forms of “paper” included papyrus and animal-skin materials like parchment and vellum. Papyrus was made from the papyrus plant, which grew in the Nile Delta in ancient Egypt. To make papyrus, strips of the plant were cut, laid into overlapping layers, and then pressed and dried into sheets. Papyrus was first used for writing as early as 2,500 B.C. and was one of the primary writing materials for thousands of years. Compared with stone, papyrus was far more data-dense; we could fit more characters on a given surface area, the substrate was lighter, and it could be folded or rolled into a scroll.
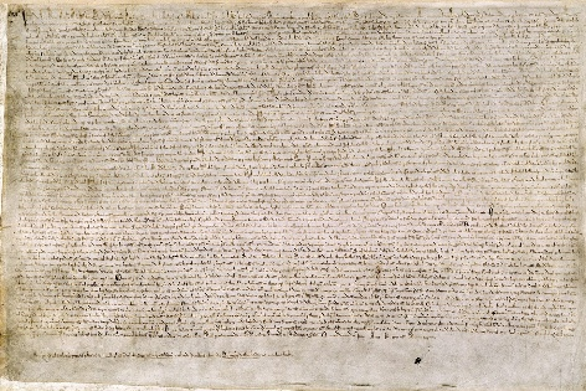
Parchment, made from cleaned and stretched animal skin, was developed long after papyrus and, thanks to its superior durability, quickly became the medium of choice for important documents. The Magna Carta, made from parchment, contains about 3,500 words or ~25,000 characters, which equates to about 200,000 bits of information. Medieval parchment weighs about 100–180 g/m², meaning the Magna Carta weighs roughly 50 grams. Using our formula, the Magna Carta’s data density comes out to around 4,000 bits/g.
Even the Magna Carta pales in comparison to modern paper with printed text. “Paper”, the flexible plant-fiber sheets we know of today, was invented in China as far back as the 2nd century B.C.. It took centuries for it to spread outside China. Paper could be made thinner and lighter than parchment or papyrus, and the printing press made it possible to fit more words on a sheet. The King James Bible, for instance, contains around 789,000 words. That’s roughly 4.3 million characters, or 34,400,000 bits of data. A standard hardcover Bible weighs about 1 kg. Even if we conservatively include the weight of the binding, the information density comes to ~34,400 bits/g, about 8.6 times the density of the Magna Carta.
Our eyesight is limited, and text can only be so small before we can no longer resolve it. The next revolution in data storage came in the form of more exotic “machine-readable” media. Examples include magnetic storage such as hard drives and magnetic tape. Here, data is encoded on magnetized material directly as bits of information – ones and zeros – by carefully controlling the polarity of magnetic domains. This technology was a wondrous breakthrough, and it’s still improving. Today, for a few hundred dollars, you can purchase a hard drive that can store tens of terabytes of data! A commercially available 10TB HDD that weighs ~1500 g can store ~80 trillion bits of data, a data density of ~53 billion bits/g, 1.54 million times higher than the King James Bible.
Yet today, hard disk drives already feel antiquated. Instead, most phones, desktops, tablets, and external drives use solid-state storage (SSDs). It’s easy to see why SSDs have become so dominant in recent years; they are ideal for mobile devices. They have no moving parts, are more durable, use less energy, and still have higher data density. Solid-state media store data by trapping electrons in a grid of floating-gate transistors to represent bits of information. A commercially available 4TB (~32 trillion bits) SSD weighs 32 grams; a data density of 1 trillion bits/g, about 19 times higher than a comparable hard drive, or about 5.3 trillion times the data density of the Rosetta Stone!
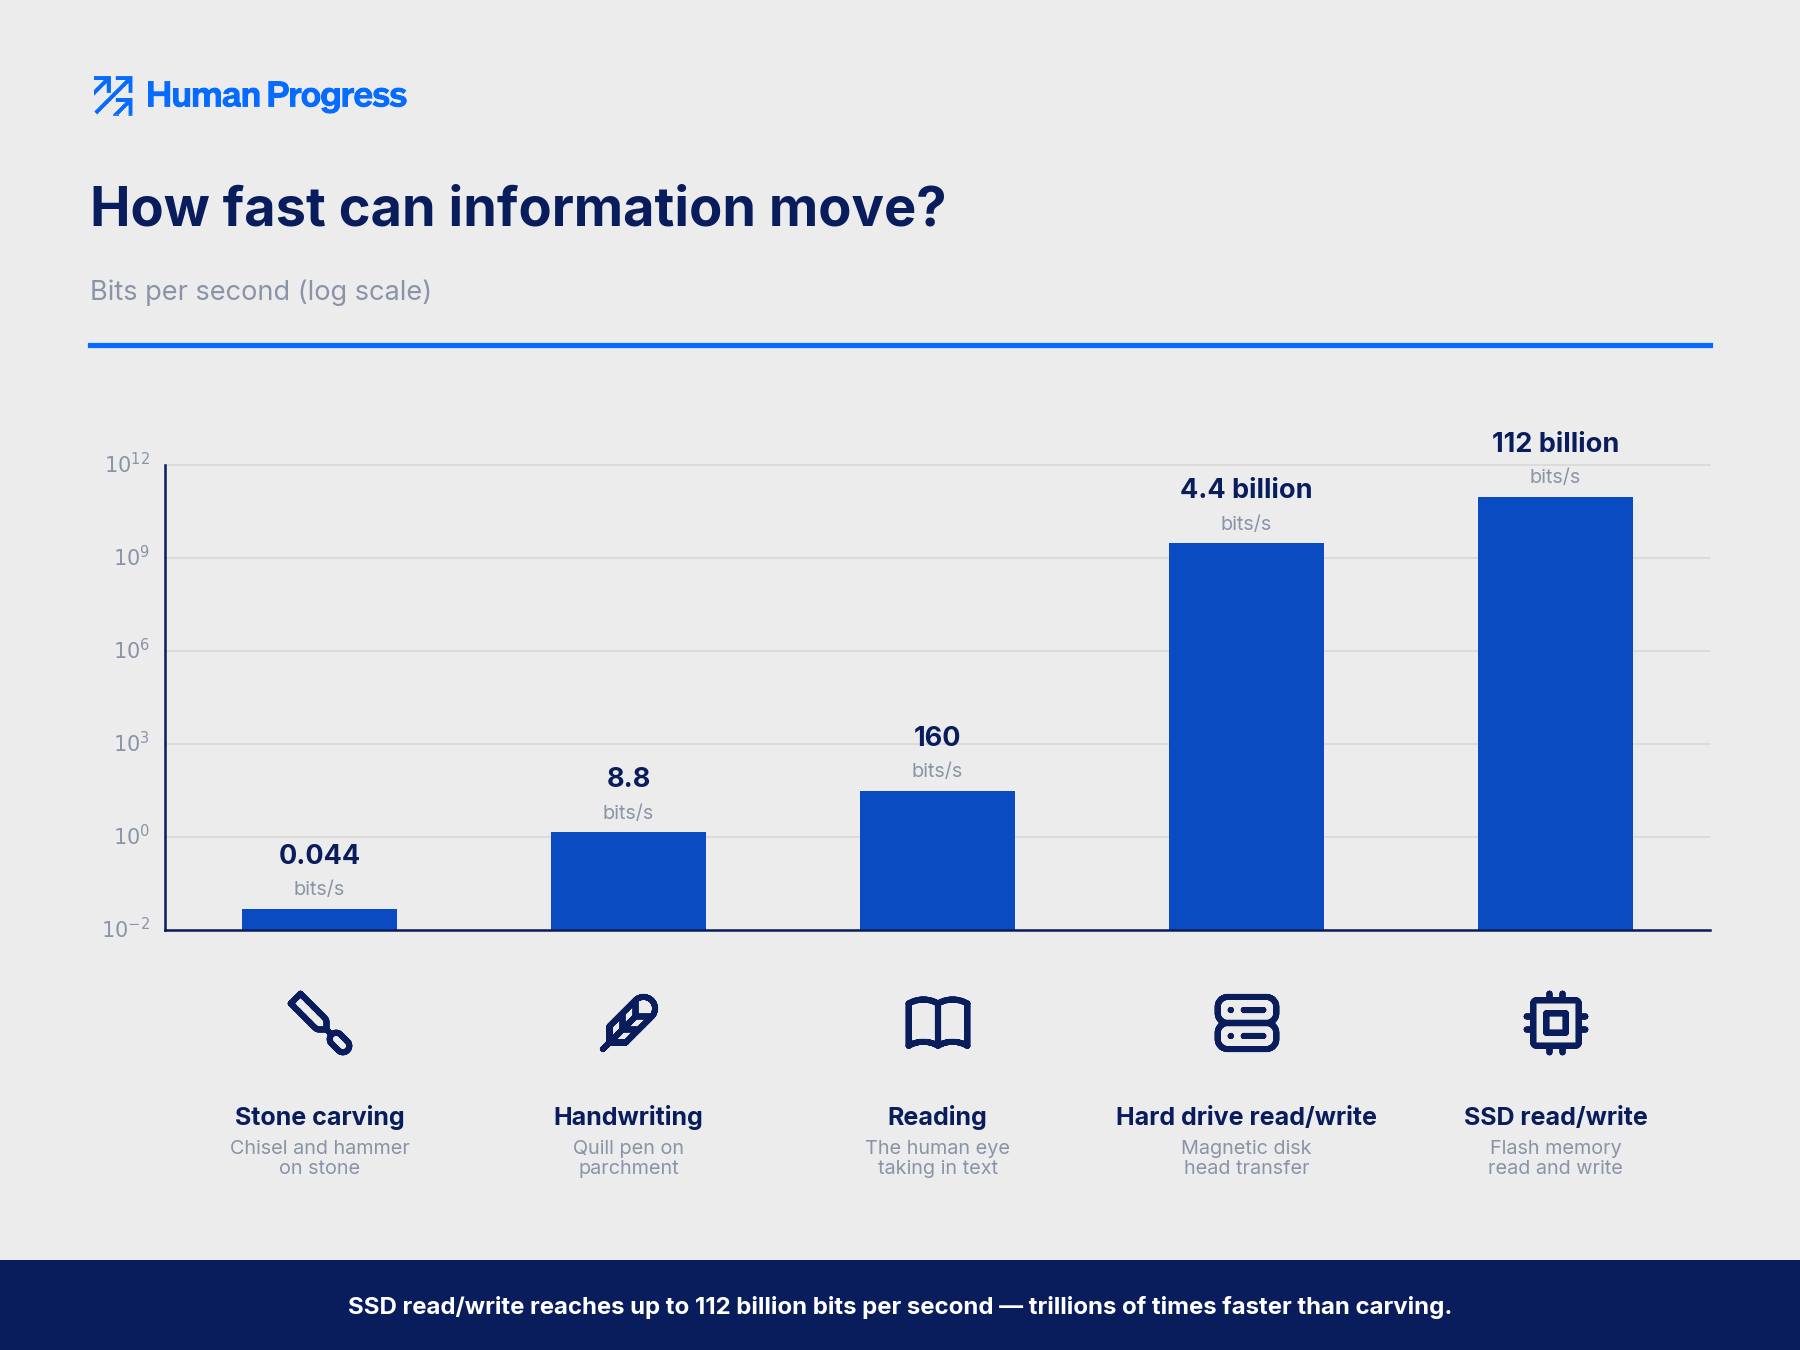
Commensurate with improvements in data density came higher read/write speeds, or “throughput.” People read about 4 words a second and with an average word length of around 5 characters; that’s about 160 bits per second. A professional stone carver might be able to write up to 20 letters an hour, or about 0.044 bits per second. Paper and paper-like media dramatically increased writing speed. A human writes about 1.1 characters per second, or roughly 8.8 bits per second – 200 times faster than carving into stone, though still slower than reading. Printing machines, of course, could print text far faster than any human could write by hand.
But none of this compares to magnetic storage, such as modern hard drives, where read/write speeds (which are similar) are currently about 4.4 billion bits per second. SSDs are faster still, reaching read/write speeds up to 112 billion bits per second. That’s about 700 million times faster than reading, and nearly 13 billion times faster than writing by hand, roughly 2.5 trillion times faster than carving into stone!
In roughly five thousand years, we’ve pushed the density of our storage media up by a factor of trillions, and the leaps keep coming faster. It took five millennia to get from stone to the printed page, representing a 180,000-fold gain in data density. In the seventy years since the invention of the hard drive, and with SSDs, humanity has multiplied that density by another 29 million times. For perspective, the text of the King James Bible carved in stone would weigh around 185 tons, nearly as much as a Boeing 747 (without fuel). On an SSD, it weighs less than a grain of sand.
AI Proposes Solution to 90-Year-Old Navier–Stokes Problem
“We’re sharing a solution to the Navier–Stokes existence and smoothness problem, one of the Millennium Prize Problems. This proof, produced by an internal OpenAI system, shows that the dynamics of the Navier-Stokes equations for fluid motion can develop a singularity in finite time. We’re sharing both a writeup of the proof and a formalization in Lean.
The Millennium Prize Problems(opens in a new window) represent some of the deepest questions at the frontier of mathematics. The question of whether smooth three-dimensional fluid motion can break down has remained unresolved for roughly 90 years.
A major goal of our work is to empower scientists to advance research and technology that benefits all of humanity. To solve the Navier–Stokes problem, we used an internal model that is significantly more capable than GPT‑6 Astra. We believe it is important to inform the world about the pace of AI progress and what to expect from upcoming models.”