01 / 05
The “ADHD Epidemic” Is Just an Overdiagnosis Epidemic

Blog Post | Mental Health

The “ADHD Epidemic” Is Just an Overdiagnosis Epidemic

Screen time gets the blame, but the increase in diagnoses comes more from subjective criteria interacting with financial incentives.

Summary: The rapid rise in ADHD diagnoses reflects expanding diagnostic criteria and financial incentives as much as any increase in impairment. Traits such as distractibility, high activity, and shifting attention often represent ordinary developmental or cognitive variation, especially among children expected to conform to rigid classroom routines. Digital media reshapes attention rather than simply damaging it, strengthening some abilities while weakening others. More reliable diagnoses require tighter criteria, independent assessments, and systems that do not create perverse financial incentives.


The sharp increase in attention-deficit/hyperactivity disorder (ADHD) diagnoses—nearly doubling among American children between 1997 and 2022, and more than tripling among adults from 2012 to 2023—has been chalked up to better screening, increased awareness, and the corrosive effects of smartphones and social media on developing brains. None of these factors holds up well under scrutiny.

The diagnostic category itself has been steadily widened by the institutions that define it and the financial structure that rewards every participant for applying the ADHD label. As we have argued in our Cato Institute analysis of how the American healthcare system rewards psychiatric overdiagnosis, subjective diagnostic criteria interact with a payment system that rewards diagnosis to produce predictable inflation across psychiatric categories. The result is labeling ordinary behavior as pathological. ADHD is among the cleanest case studies of that pattern.

Foraging minds in an industrial classroom.

Human cognition was shaped over hundreds of thousands of years in small foraging bands, where attentional flexibility was an asset rather than a liability. A child who scanned the horizon, registered novel stimuli, and shifted focus rapidly between threats and opportunities was a child more likely to survive. Sustained, narrowly channeled attention to a single abstract task for hours at a time was simply not part of the ancestral environment, and the cognitive machinery to produce such concentration on demand was never uniformly selected for. What we now call distractibility is, in another light, vigilance. Most animals, including ancestral humans, evolved to be constantly on the lookout for novelty and threat.

Mass schooling, which emerged in the 19th century in part to prepare children for industrial labor, asks something quite different. It asks 6- and 7‑year-olds to sit still in rows, suppress physical movement, attend to a single voice for extended stretches, and produce written output on a fixed schedule. Most children adapt. The variance in how easily they do so is enormous, and the children at the lower tail of conformity to that demand have come to define the diagnostic category.

Boys end up there more often than girls, for reasons that are not mysterious. Boys, on average, are more physically active, take longer to develop self-control, and are more drawn to rough play. The same pattern shows up in other mammals and tracks the effects of testosterone on brain development. Put boys in a room and tell them to sit still for six hours, and a predictable share of them will fail, not because they are mentally ill but because they are boys. The youngest children in any classroom are also more likely to be diagnosed with ADHD than their older peers, a finding so robust across studies and countries that it points to ordinary developmental variation rather than disease.

The evolutionary frame also provides a more nuanced understanding of the fear that screen time in childhood harms brain development and attention span. The brain is plastic, especially in childhood, and it adapts to the environment it is given. That plasticity is precisely what allowed generations raised under modern industrialized education systems to develop the sustained attention style that schools reward, despite it being so far from our environment of evolutionary adaptedness. But a generation that grows up navigating fast-moving feeds, switching between applications, and processing rapid streams of visual information will predictably develop a different attentional profile than one raised on books and chalkboards.

That does not mean the learning or attention span of youth raised on digital technology is impaired. Heavy media multitaskers and habitual users of touchscreen devices do tend to perform worse on tasks that demand sustained, narrowly focused attention and inhibitory control. But they also tend to perform better on tasks that demand rapid visual search, parallel processing of multiple objects, and flexible reallocation of attention. Action video game play, in particular, has been shown to enhance visual selective attention, processing speed, and the spatial resolution of vision. These effects transfer beyond the trained task, improving general abilities to track several moving things at once, spot relevant objects in a crowded scene, and pick out a target faster when surrounded by distractions.

These cognitive trade-offs elucidate how neural plasticity gives rise to different forms of intelligence. The brain has a finite budget of computational and metabolic resources, and the cortex reallocates them in response to the demands placed on it. The clearest demonstrations come from sensory deprivation: In people who lose their sight, the visual cortex does not simply lie fallow but is recruited for auditory and tactile processing, including Braille reading, with measurable gains in those domains. Congenitally deaf individuals show analogous repurposing of the auditory cortex for vision and smell. Every brain is continuously specializing toward whatever it does most, and different cognitive skillsets have different trade-offs.

A brain trained on rapid feeds and parallel streams gets better at rapid visual search, switching, and parallel processing while getting worse at slow, serial, endogenous focus. A brain trained on long books and chalkboards makes the opposite trade. The picture is not simply that screens damage children’s brains or lower their intelligence. Claims of generalized cognitive harm typically rest on measures of a single attentional style, the one schools happen to demand, and ignore the capacities that grow on the other side of the ledger. Calling the resulting attentional profile ADHD, treating it as a chronic illness, and medicating it accordingly is a category error. The trade-offs are real, but the diagnostic system measures only the deficits because only the deficits are reimbursable.

From hyperkinetic boys to inattentive adults.

The diagnostic category we now call ADHD has been progressively widened almost from the moment it entered the Diagnostic and Statistical Manual of Mental Disorders, the reference text published by the American Psychiatric Association that defines the criteria for every recognized psychiatric condition in the United States. The DSM-II, published in 1968, listed the condition as “hyperkinetic reaction of childhood” and described it in a single sentence, focused on the restless, disruptive child, almost always identified as a boy, who would supposedly grow out of the condition by adolescence. The DSM-III, in 1980, renamed it attention deficit disorder, with or without hyperactivity, and for the first time treated inattention as a stand-alone presentation rather than a symptom of restlessness. That single revision opened the category to a far larger population of children, especially girls, whose attentional patterns had previously been invisible to the diagnostic system.

The DSM-III‑R, in 1987, folded the subtypes back together and introduced the current acronym, ADHD. The DSM-IV, in 1994, separated the disorder again into three presentations—predominantly inattentive, predominantly hyperactive-impulsive, and combined—and explicitly extended the diagnosis into social, academic, and vocational contexts beyond childhood. Studies comparing the DSM-III‑R and DSM-IV criteria directly found that prevalence rose from 9.6 to 17.8 percent under one set of comparisons and from 7.3 to 11.4 percent under another, almost entirely on the strength of newly identified inattentive cases. The DSM‑5, in 2013, raised the age-of-onset requirement from 7 to 12 and lowered the symptom threshold for adults.

Each revision expanded the population eligible for diagnosis, and, with it, the population eligible for stimulant prescriptions, academic accommodations, and disability protections. The trajectory runs in one direction. There is no edition of the DSM in which the criteria for ADHD became more restrictive.

The incentive problem.

Layered atop the definitional and developmental story is a set of economic incentives that quietly lower the threshold for diagnosis. A growing share of these diagnoses now comes from primary care clinicians rather than specialists, reflecting how rapidly ADHD treatment has migrated into routine primary care, and how the expansion of telehealth lowered the friction of obtaining a prescription.

One of the clearest examples of incentives for overdiagnosis comes from how we finance education. When special-education funding is tied to specific diagnoses, schools have a built-in reason to identify more students with ADHD, because the label unlocks additional resources. Researchers have documented systematic differences in diagnosis and treatment that align with funding formulas rather than with underlying disease rates, a pattern consistent with third-party financial incentives shaping who gets labeled. Clinicians do not work in isolation; they respond to expectations from schools, families, and the broader system. Once stakeholders recognize that a diagnosis unlocks services, pressure to apply the label tends to grow.

Primary care clinicians typically practice in fee-for-service systems, where assigning a diagnosis makes the encounter billable and enables reimbursement for follow-up visits and medication management. Patients have their own incentives to seek the diagnosis, including academic accommodations, workplace protections, and access to performance-enhancing stimulants such as Adderall. In an environment where the condition is defined by subjective criteria rather than objective tests, it is unsurprising that some individuals exaggerate or feign symptoms to obtain those benefits.

The pattern is by now familiar. As we documented in our analysis of Medicaid-funded autism therapy, the broadening of autism criteria, combined with open-ended reimbursement, produced an explosion in spending on applied behavior analysis that far outpaced any plausible change in the prevalence of disabling autism. The broadening of ADHD criteria has produced a parallel surge in stimulant prescriptions, and our recent piece against the campaign to formalize “social media addiction” anticipates the same trajectory if that diagnosis is formalized. In each case, subjective diagnosis and financial incentives that reward diagnosis push the boundaries of illness outward.

What this should teach us.

The growth in diagnoses is best understood as the cumulative output of several systems, each behaving in a way its incentives reward. Definitions expand because there is little institutional pressure to keep them tight. Clinicians diagnose because diagnosis is what the system pays for. Schools refer because referrals bring resources. Patients seek labels because labels bring access to special accommodations. The aggregate effect is a steady erosion of the line between ordinary human variation and clinical disease.

That erosion has costs. Children whose ordinary inattentiveness is medicated as a chronic condition, adults who organize their identities around a label, and patients with severely impairing ADHD whose treatment resources are diluted across an ever-larger pool all bear those costs. The path to more reliable diagnoses runs through more reliable incentives: tighter criteria, independent assessments, and payment structures that do not reward expanding the definition of illness. Policymakers should stop structuring schools, insurers, and healthcare systems so that people must acquire a medical diagnosis to receive help, accommodations, or reimbursement.

Children today have greater safety, resource availability, and tools for education than any cohort in human history. It is the schoolroom that asks kids to sit still for hours and the diagnostic system that pathologizes the ones who cannot that are the more unusual and pathological features of modernity. A more honest accounting would distinguish severely impairing attentional disorders from the wider band of ordinary human variation. It would recognize that the temperaments now most likely to be medicalized are, in a different setting, the temperaments that helped aid survival and human progress.

This article originally appeared in The Dispatch on 5/13/2026.

The Keyword | Scientific Research

AI Atlas Predicts Effects of Human DNA Changes

“The human genome is made of about 3 billion base pairs of DNA — but much of it remains a mystery. Scientists understand the 2% of the human genome that codes for proteins relatively well, but have only limited knowledge of the remaining 98%. Our AlphaGenome model has already shown how single changes in these non-coding DNA regions can disrupt molecular processes like protein production, but the bigger picture remained unclear.

Today, we're introducing AlphaGenome Atlas, a database that predicts the effects of every possible single nucleotide variant in the human genome. We used the AlphaGenome AI model to pre-calculate the regulatory impact of all 9 billion single-letter genetic changes, resulting in a massive, 1-petabyte dataset. Our new Atlas helps scientists rapidly query this vast information.

To help researchers rapidly navigate this, the Atlas introduces the AlphaGenome Variant Impact (AVI) score. This single, easy-to-use score combines predictions for both coding and non-coding regions, allowing researchers to quickly prioritize the most promising avenues for research without sifting through thousands of data points.”

From The Keyword.

Wall Street Journal | Scientific Research

New $1 Million Prize Rewards Academic Truth-Telling

“Mr. Fryer raised the alarm about suppression of inconvenient findings in a November 2024 Wall Street Journal essay. He called for something like a MacArthur Fellowship or an X Prize for academic truth-telling. The prize should be large enough to matter, prestigious enough to serve as a public credential for scholars who were right when it was costly to be right. Shortly after that piece ran, we found each other and decided to launch the Carob Trust Prize for Academic Courage.

The prize awards $1 million each to as many as five social scientists a year who have demonstrated intellectual independence, published findings that were attacked rather than answered, and been validated by the evidence—despite the professional cost. The selection criteria are designed to distinguish courage from contrarianism: Nominees must show a sustained commitment to following logic and evidence regardless of pressure, a willingness to ask questions others avoid, and work that has shifted academic debate, public discourse or policy—often despite being misread, mischaracterized or vilified at the time of publication.

The inaugural prize is limited to the social sciences; in future years we hope to broaden it to additional disciplines and to add a category for institutional leadership. Nominations are open through Nov. 1, and the first winners will be announced in early 2027.”

From Wall Street Journal.

Blog Post | Human Development

From Stone Tablets to Solid-State Drives

Civilization has advanced by learning to preserve more knowledge with less matter.

Summary: Human progress depends not only on discovering knowledge but also on preserving and transmitting it. From stone tablets to printed books and solid-state drives, storage media have become vastly lighter, denser, and faster. Over five thousand years, humanity has increased data density by trillions, making accumulated knowledge cheaper and more accessible than ever.


The astonishing conveniences and prosperity of modern civilization rest on two pillars: our mastery of energy and our relentless discovery of knowledge. Yet, discovering new knowledge alone was not enough for civilizational progress. To accumulate and build on discoveries across generations, humanity needed a way to encode knowledge onto a medium outside of our collective nervous system. From etching hieroglyphs into stone to digitally controlling electrons in modern solid-state drives (SSDs), humanity’s advancement in creating affordable, lightweight, and reliable data storage is astonishing.

Before the invention of written language, people usually transmitted knowledge orally. Fables and other knowledge had to be memorized and accurately recited to pass from one generation to the next. Transmitting knowledge this way, where data is stored only in the human mind, risks significant data loss. When Joe Huntergatherer, the only member of the tribe who had memorized the story of the Great Elder, was killed by an arrow, that story was forever lost. The fragility of oral transmission is why almost all human history, spanning hundreds of thousands of years, is lost to the erosive sands of time.

The invention of writing, the ability to etch, carve, or paint characters onto clay tablets, stone, and cave walls, allowed humans, for the first time, to store information outside the brain. The first clay inscriptions with readable script date from ~3,400 B.C. So long as another person was trained to interpret the inscribed hieroglyphs, characters, or letters, that knowledge was no longer subject to fallible human memory. However, stone inscriptions had relatively low information density.

To create a formula to measure the data density of storage media over time, I convert characters (letters and punctuation) into bits of information, then divide by the number of grams of matter needed to encode that information. A bit is a single binary digit, a zero or one, and roughly eight bits make up a single character. (View these calculations not as precise figures, but as order-of-magnitude approximations, since data density varies considerably from stone to book to drive.)

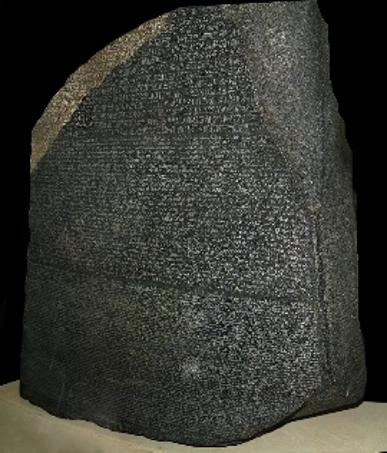
Let’s begin with stone engravings, using the famous Rosetta Stone as an example. The Rosetta Stone weighs roughly 750kg and contains the same text in three languages: Ancient Egyptian hieroglyphs on top, Egyptian Demotic script in the middle, and Ancient Greek on the bottom. To estimate the data density, I focused on the Greek portion of the stone, which accounts for roughly 1/3 of the stone’s total weight (about 250kg).

No source I could find provided a reliable count of the surviving Greek characters, so I calculated it twice independently. First, I compared a 19th-century publication’s line-by-line count with a high-resolution photo of the stone, which puts the original, undamaged text at about ~7,290 characters. Adjusting that figure for the approximately 20 percent of the stone that’s damaged or missing gives an estimated ~5,832 surviving characters. Second, I ran an AI optical character count directly off the damaged stone, which returned ~5,800. The two methods are close, so I use ~5,800 characters going forward.

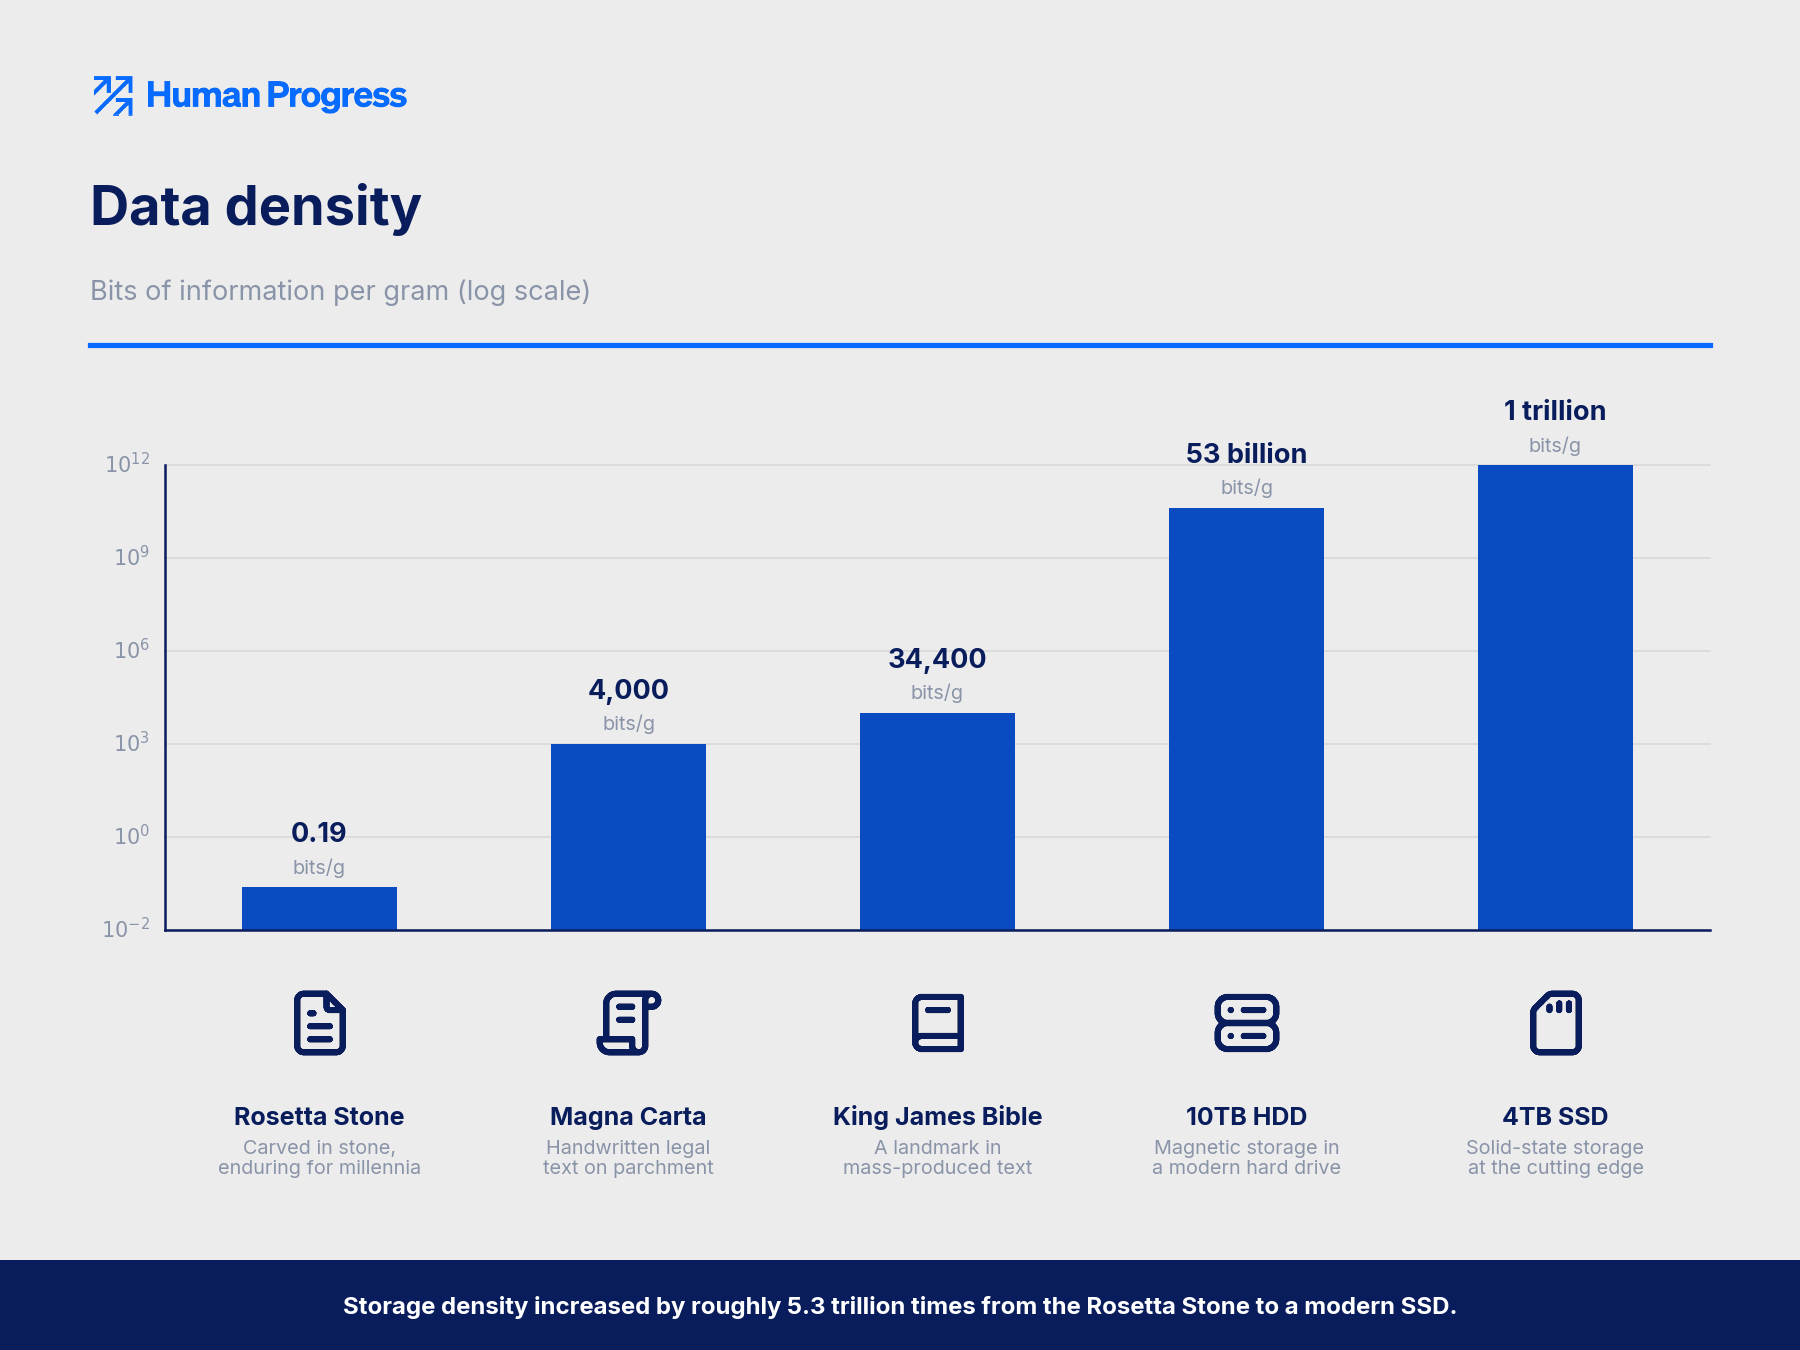
Since a single character of text equates to about 8 bits of information, the surviving 5,800 characters store 46,400 bits of data. Divided by the 250kg weight of the Greek portion, we arrive at a data density for the Rosetta Stone of ~0.19 bits/g.

With the discovery of agriculture and the rise of agrarian civilizations, the demands for knowledge storage and transmission media grew. The human population expanded, and a small but notable fraction began to congregate in small towns. As social and economic complexity grew, so did administration, trade, tax, and legal systems. Humans needed an easy way to perform and store the outputs of mathematical calculations, record taxes, and codify rules and regulations for personal and business conduct. Agrarian civilization, in short, demanded a storage medium with higher information density and faster read/write speeds (throughput). Enter papyrus, parchment, and paper.

Early forms of “paper” included papyrus and animal-skin materials like parchment and vellum. Papyrus was made from the papyrus plant, which grew in the Nile Delta in ancient Egypt. To make papyrus, strips of the plant were cut, laid into overlapping layers, and then pressed and dried into sheets. Papyrus was first used for writing as early as 2,500 B.C. and was one of the primary writing materials for thousands of years. Compared with stone, papyrus was far more data-dense; we could fit more characters on a given surface area, the substrate was lighter, and it could be folded or rolled into a scroll.

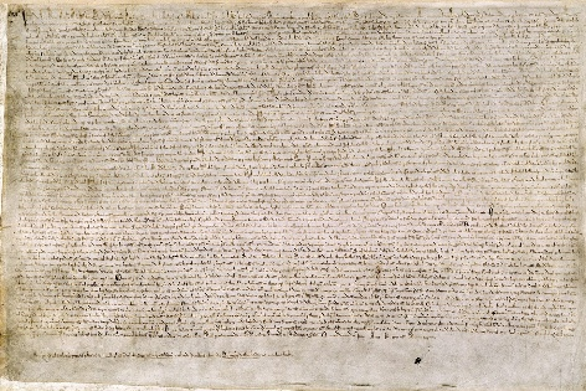
Parchment, made from cleaned and stretched animal skin, was developed long after papyrus and, thanks to its superior durability, quickly became the medium of choice for important documents. The Magna Carta, made from parchment, contains about 3,500 words or ~25,000 characters, which equates to about 200,000 bits of information. Medieval parchment weighs about 100–180 g/m², meaning the Magna Carta weighs roughly 50 grams. Using our formula, the Magna Carta’s data density comes out to around 4,000 bits/g.

Even the Magna Carta pales in comparison to modern paper with printed text. “Paper”, the flexible plant-fiber sheets we know of today, was invented in China as far back as the 2nd century B.C.. It took centuries for it to spread outside China. Paper could be made thinner and lighter than parchment or papyrus, and the printing press made it possible to fit more words on a sheet. The King James Bible, for instance, contains around 789,000 words. That’s roughly 4.3 million characters, or 34,400,000 bits of data. A standard hardcover Bible weighs about 1 kg. Even if we conservatively include the weight of the binding, the information density comes to ~34,400 bits/g, about 8.6 times the density of the Magna Carta.

Our eyesight is limited, and text can only be so small before we can no longer resolve it. The next revolution in data storage came in the form of more exotic “machine-readable” media. Examples include magnetic storage such as hard drives and magnetic tape. Here, data is encoded on magnetized material directly as bits of information – ones and zeros – by carefully controlling the polarity of magnetic domains. This technology was a wondrous breakthrough, and it’s still improving. Today, for a few hundred dollars, you can purchase a hard drive that can store tens of terabytes of data! A commercially available 10TB HDD that weighs ~1500 g can store ~80 trillion bits of data, a data density of ~53 billion bits/g, 1.54 million times higher than the King James Bible.

Yet today, hard disk drives already feel antiquated. Instead, most phones, desktops, tablets, and external drives use solid-state storage (SSDs). It’s easy to see why SSDs have become so dominant in recent years; they are ideal for mobile devices. They have no moving parts, are more durable, use less energy, and still have higher data density. Solid-state media store data by trapping electrons in a grid of floating-gate transistors to represent bits of information. A commercially available 4TB (~32 trillion bits) SSD weighs 32 grams; a data density of 1 trillion bits/g, about 19 times higher than a comparable hard drive, or about 5.3 trillion times the data density of the Rosetta Stone!

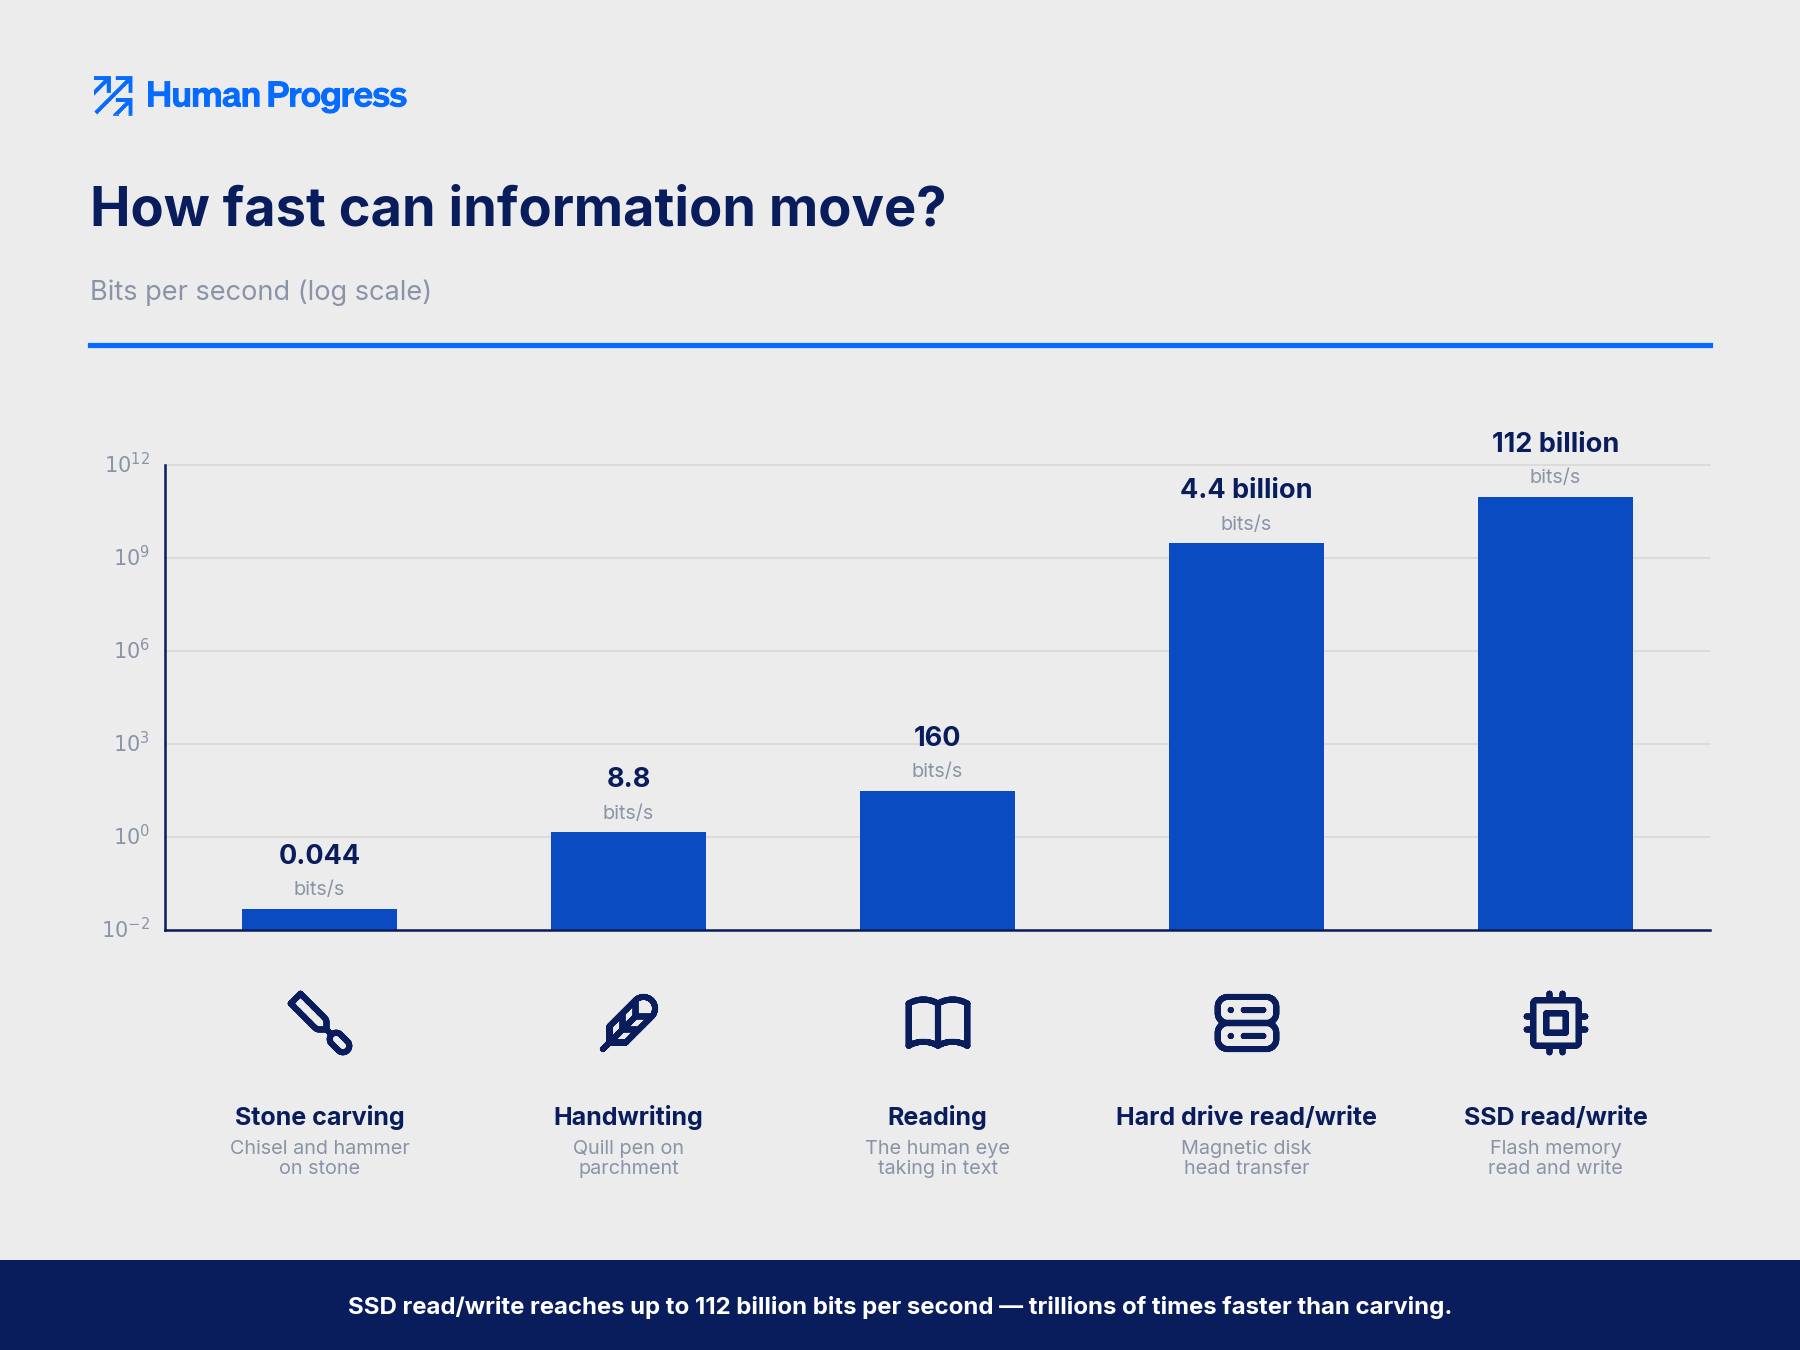
Commensurate with improvements in data density came higher read/write speeds, or “throughput.” People read about 4 words a second and with an average word length of around 5 characters; that’s about 160 bits per second. A professional stone carver might be able to write up to 20 letters an hour, or about 0.044 bits per second. Paper and paper-like media dramatically increased writing speed. A human writes about 1.1 characters per second, or roughly 8.8 bits per second – 200 times faster than carving into stone, though still slower than reading. Printing machines, of course, could print text far faster than any human could write by hand.

But none of this compares to magnetic storage, such as modern hard drives, where read/write speeds (which are similar) are currently about 4.4 billion bits per second. SSDs are faster still, reaching read/write speeds up to 112 billion bits per second. That’s about 700 million times faster than reading, and nearly 13 billion times faster than writing by hand, roughly 2.5 trillion times faster than carving into stone!

In roughly five thousand years, we’ve pushed the density of our storage media up by a factor of trillions, and the leaps keep coming faster. It took five millennia to get from stone to the printed page, representing a 180,000-fold gain in data density. In the seventy years since the invention of the hard drive, and with SSDs, humanity has multiplied that density by another 29 million times. For perspective, the text of the King James Bible carved in stone would weigh around 185 tons, nearly as much as a Boeing 747 (without fuel). On an SSD, it weighs less than a grain of sand.

OpenAI | Scientific Research

AI Proposes Solution to 90-Year-Old Navier–Stokes Problem

“We’re sharing a solution to the Navier–Stokes existence and smoothness problem, one of the Millennium Prize Problems. This proof, produced by an internal OpenAI system, shows that the dynamics of the Navier-Stokes equations for fluid motion can develop a singularity in finite time. We’re sharing both a writeup of the proof and a formalization in Lean.

The Millennium Prize Problems⁠(opens in a new window) represent some of the deepest questions at the frontier of mathematics. The question of whether smooth three-dimensional fluid motion can break down has remained unresolved for roughly 90 years.

A major goal of our work is to empower scientists to advance research and technology that benefits all of humanity. To solve the Navier–Stokes problem, we used an internal model that is significantly more capable than GPT‑6 Astra. We believe it is important to inform the world about the pace of AI progress and what to expect from upcoming models.”

From OpenAI.