AI Models Went from $100 Million to $5 Million Then to $30 in Seven Days
What a week for innovation.
Gale L. Pooley —
Summary: The rapid decline in AI model costs is reshaping the field, with UC Berkeley researchers replicating DeepSeek’s $5 million AI for just $30 in a matter of days. They demonstrated that cutting-edge AI development no longer requires massive budgets—only the right approach. This breakthrough highlights how disruptive innovation is accelerating at an unprecedented pace, making technology more accessible than ever before.
We noted recently that DeepSeek had created an artificial intelligence (AI) model for around $5 million that matched the performance of OpenAI’s $100 million model. Now we learn that a research team at the University of California, Berkeley (UC Berkeley) has reportedly re-created the core technology behind DeepSeek for just $30.
According to Brian Roemmele, UC Berkeley PhD candidate Jiayi Pan and his team replicated DeepSeek R1-Zero’s reinforcement learning capabilities using a compact language model called TinyZero. This open-source reinforcement learning engine utilizes the self-play learning paradigm, originally pioneered by DeepMind in the development of AlphaZero, to achieve mastery of the games of chess, shogi, and go.
The stunningly low cost of this replication underscores a growing trend: While tech giants pour vast sums into AI development, open-source and independent researchers are proving that high-performance AI can be built at a fraction of the cost. In fact, TinyZero is freely available for download on GitHub.
The TinyZero program achieved DeepSeek-level performance by renting two H200 Nvidia chips for under five hours at just $6.40 per hour.
Their success in implementing sophisticated reasoning capabilities in small language models marks a significant democratization of AI research. . . . Richard Sutton, the father of reinforcement learning, would likely find vindication in these results. They align with his vision of continuous learning as the key to AI advancement, demonstrating that sophisticated AI capabilities can emerge from relatively simple systems given the right learning framework. . . . This work from a Chinese AI research company may well mark a turning point in AI development, proving that groundbreaking advances don’t require massive resources—just clever thinking and the right approach.
To put this breakthrough in perspective, the telegraph reduced the time it took the Pony Express to deliver a message from St. Joseph, Missouri, to Sacramento, California, by 99.93 percent—from 10 days to 10 minutes. Pan’s $30 TinyZero program slashed the cost of DeepSeek’s $5 million model by 99.9994 percent. For the price of a single DeepSeek model, you can build 166,667 TinyZero models.
Disruptive innovation is disrupting disruptive innovation. Clayton Christensen, originator of the “disruptive innovation” theory, would be pleased. Meanwhile, the $500 billion Stargate AI infrastructure initiative, announced 10 days ago, already looks obsolete. Human intelligence continues to discover ever more efficient ways of teaching AI how to learn. Hang on—this revolution is just beginning.
Find more of Gale’s work at his Substack, Gale Winds.
Civilization has advanced by learning to preserve more knowledge with less matter.
J.K. Lundblad —
Summary: Human progress depends not only on discovering knowledge but also on preserving and transmitting it. From stone tablets to printed books and solid-state drives, storage media have become vastly lighter, denser, and faster. Over five thousand years, humanity has increased data density by trillions, making accumulated knowledge cheaper and more accessible than ever.
The astonishing conveniences and prosperity of modern civilization rest on two pillars: our mastery of energy and our relentless discovery of knowledge. Yet, discovering new knowledge alone was not enough for civilizational progress. To accumulate and build on discoveries across generations, humanity needed a way to encode knowledge onto a medium outside of our collective nervous system. From etching hieroglyphs into stone to digitally controlling electrons in modern solid-state drives (SSDs), humanity’s advancement in creating affordable, lightweight, and reliable data storage is astonishing.
Before the invention of written language, people usually transmitted knowledge orally. Fables and other knowledge had to be memorized and accurately recited to pass from one generation to the next. Transmitting knowledge this way, where data is stored only in the human mind, risks significant data loss. When Joe Huntergatherer, the only member of the tribe who had memorized the story of the Great Elder, was killed by an arrow, that story was forever lost. The fragility of oral transmission is why almost all human history, spanning hundreds of thousands of years, is lost to the erosive sands of time.
The invention of writing, the ability to etch, carve, or paint characters onto clay tablets, stone, and cave walls, allowed humans, for the first time, to store information outside the brain. The first clay inscriptions with readable script date from ~3,400 B.C. So long as another person was trained to interpret the inscribed hieroglyphs, characters, or letters, that knowledge was no longer subject to fallible human memory. However, stone inscriptions had relatively low information density.
To create a formula to measure the data density of storage media over time, I convert characters (letters and punctuation) into bits of information, then divide by the number of grams of matter needed to encode that information. A bit is a single binary digit, a zero or one, and roughly eight bits make up a single character. (View these calculations not as precise figures, but as order-of-magnitude approximations, since data density varies considerably from stone to book to drive.)
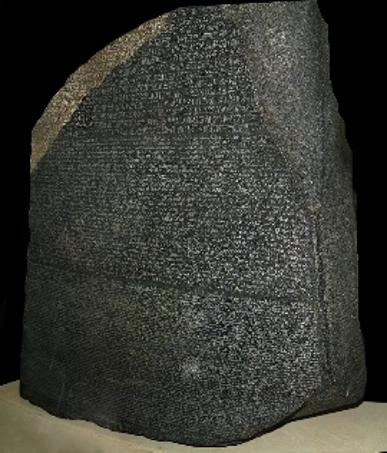
Let’s begin with stone engravings, using the famous Rosetta Stone as an example. The Rosetta Stone weighs roughly 750kg and contains the same text in three languages: Ancient Egyptian hieroglyphs on top, Egyptian Demotic script in the middle, and Ancient Greek on the bottom. To estimate the data density, I focused on the Greek portion of the stone, which accounts for roughly 1/3 of the stone’s total weight (about 250kg).
No source I could find provided a reliable count of the surviving Greek characters, so I calculated it twice independently. First, I compared a 19th-century publication’s line-by-line count with a high-resolution photo of the stone, which puts the original, undamaged text at about ~7,290 characters. Adjusting that figure for the approximately 20 percent of the stone that’s damaged or missing gives an estimated ~5,832 surviving characters. Second, I ran an AI optical character count directly off the damaged stone, which returned ~5,800. The two methods are close, so I use ~5,800 characters going forward.
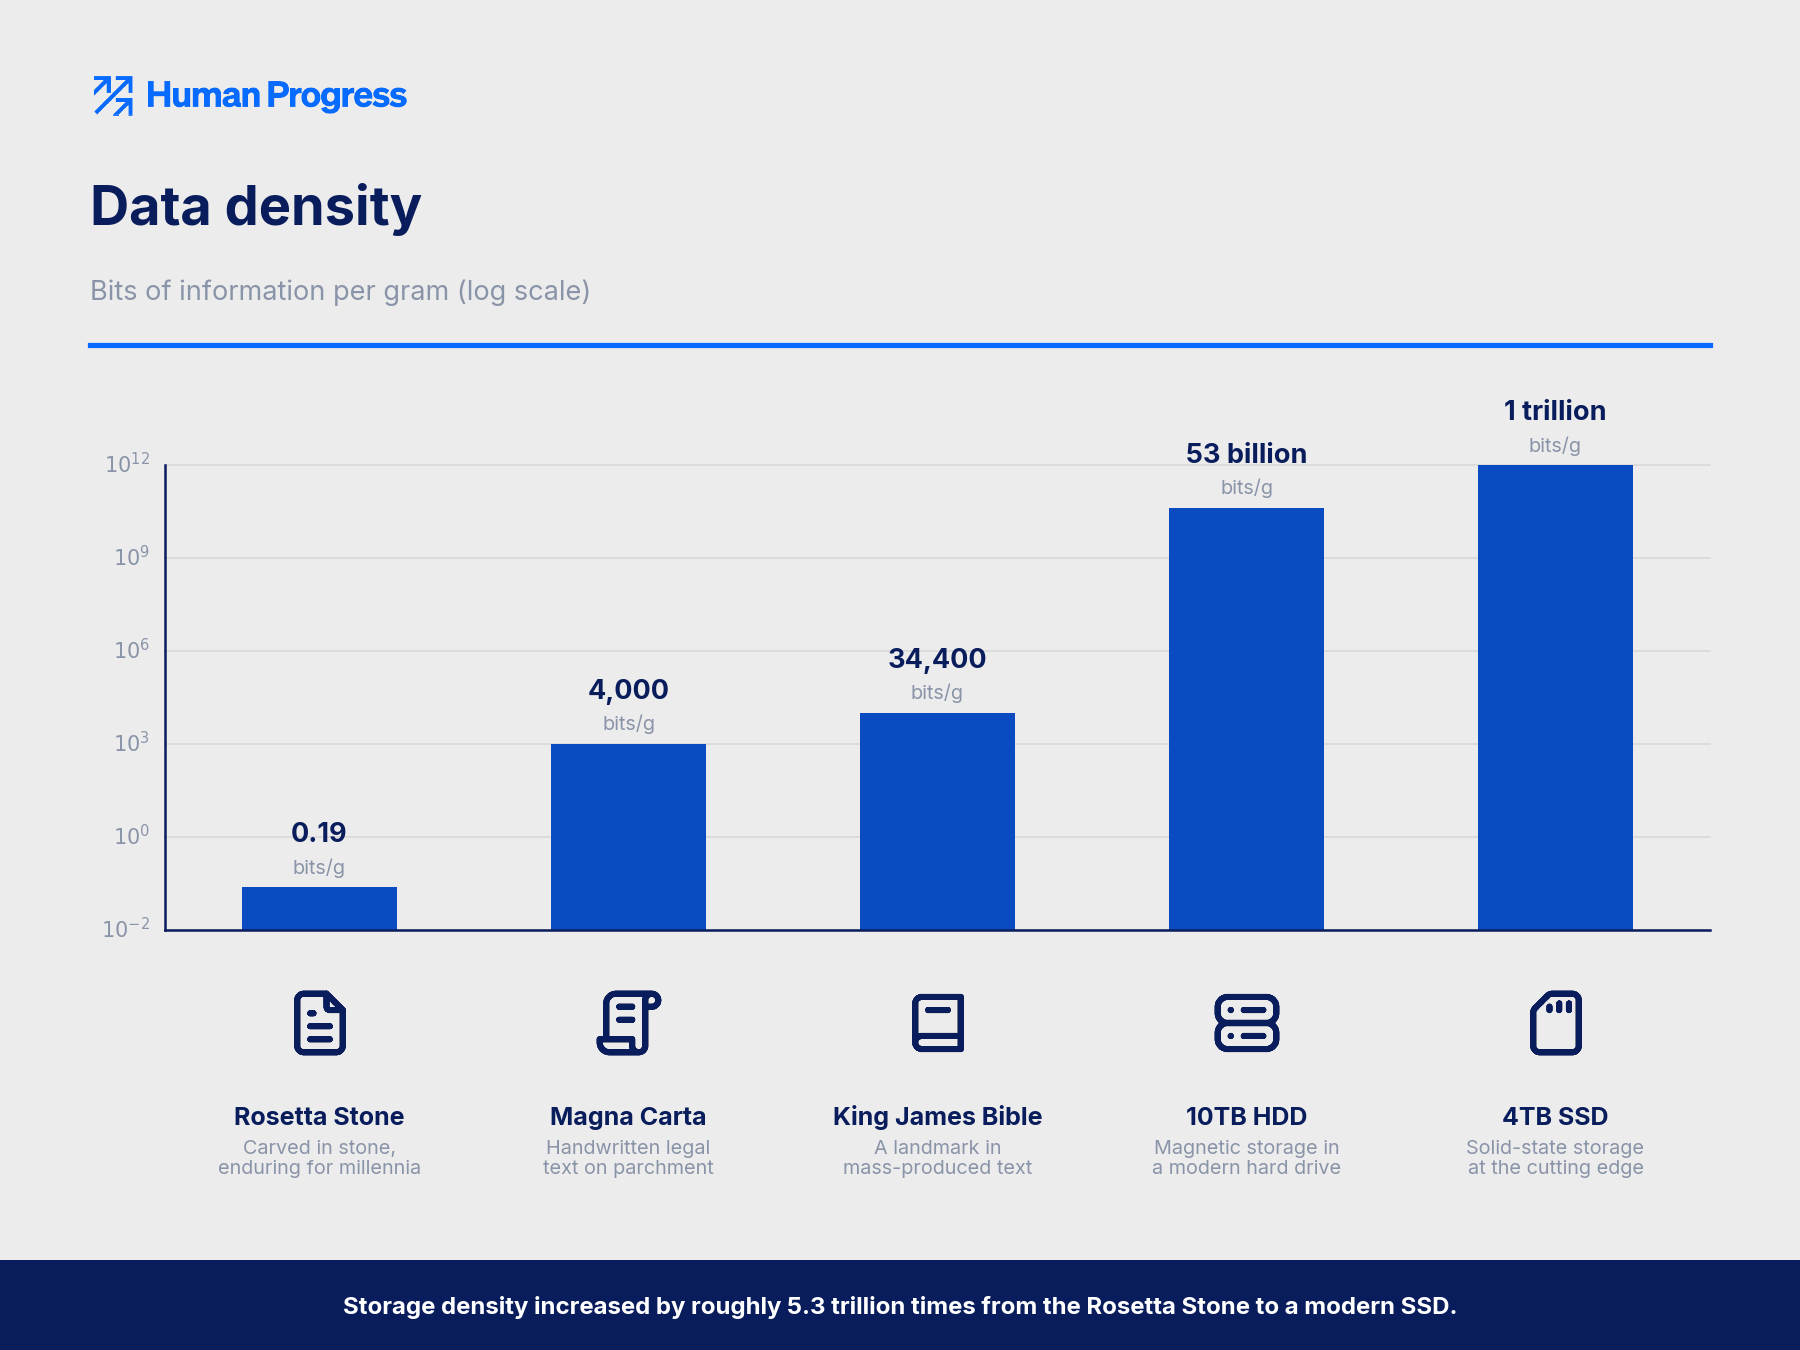
Since a single character of text equates to about 8 bits of information, the surviving 5,800 characters store 46,400 bits of data. Divided by the 250kg weight of the Greek portion, we arrive at a data density for the Rosetta Stone of ~0.19 bits/g.
With the discovery of agriculture and the rise of agrarian civilizations, the demands for knowledge storage and transmission media grew. The human population expanded, and a small but notable fraction began to congregate in small towns. As social and economic complexity grew, so did administration, trade, tax, and legal systems. Humans needed an easy way to perform and store the outputs of mathematical calculations, record taxes, and codify rules and regulations for personal and business conduct. Agrarian civilization, in short, demanded a storage medium with higher information density and faster read/write speeds (throughput). Enter papyrus, parchment, and paper.
Early forms of “paper” included papyrus and animal-skin materials like parchment and vellum. Papyrus was made from the papyrus plant, which grew in the Nile Delta in ancient Egypt. To make papyrus, strips of the plant were cut, laid into overlapping layers, and then pressed and dried into sheets. Papyrus was first used for writing as early as 2,500 B.C. and was one of the primary writing materials for thousands of years. Compared with stone, papyrus was far more data-dense; we could fit more characters on a given surface area, the substrate was lighter, and it could be folded or rolled into a scroll.
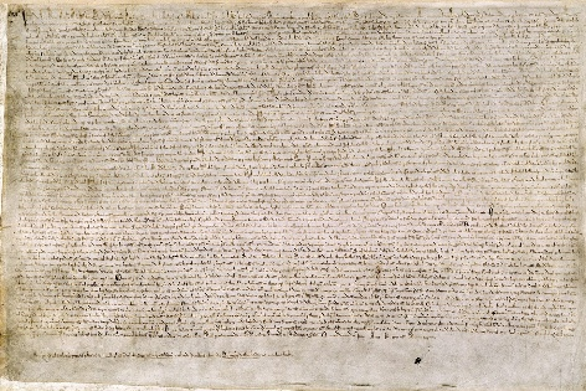
Parchment, made from cleaned and stretched animal skin, was developed long after papyrus and, thanks to its superior durability, quickly became the medium of choice for important documents. The Magna Carta, made from parchment, contains about 3,500 words or ~25,000 characters, which equates to about 200,000 bits of information. Medieval parchment weighs about 100–180 g/m², meaning the Magna Carta weighs roughly 50 grams. Using our formula, the Magna Carta’s data density comes out to around 4,000 bits/g.
Even the Magna Carta pales in comparison to modern paper with printed text. “Paper”, the flexible plant-fiber sheets we know of today, was invented in China as far back as the 2nd century B.C.. It took centuries for it to spread outside China. Paper could be made thinner and lighter than parchment or papyrus, and the printing press made it possible to fit more words on a sheet. The King James Bible, for instance, contains around 789,000 words. That’s roughly 4.3 million characters, or 34,400,000 bits of data. A standard hardcover Bible weighs about 1 kg. Even if we conservatively include the weight of the binding, the information density comes to ~34,400 bits/g, about 8.6 times the density of the Magna Carta.
Our eyesight is limited, and text can only be so small before we can no longer resolve it. The next revolution in data storage came in the form of more exotic “machine-readable” media. Examples include magnetic storage such as hard drives and magnetic tape. Here, data is encoded on magnetized material directly as bits of information – ones and zeros – by carefully controlling the polarity of magnetic domains. This technology was a wondrous breakthrough, and it’s still improving. Today, for a few hundred dollars, you can purchase a hard drive that can store tens of terabytes of data! A commercially available 10TB HDD that weighs ~1500 g can store ~80 trillion bits of data, a data density of ~53 billion bits/g, 1.54 million times higher than the King James Bible.
Yet today, hard disk drives already feel antiquated. Instead, most phones, desktops, tablets, and external drives use solid-state storage (SSDs). It’s easy to see why SSDs have become so dominant in recent years; they are ideal for mobile devices. They have no moving parts, are more durable, use less energy, and still have higher data density. Solid-state media store data by trapping electrons in a grid of floating-gate transistors to represent bits of information. A commercially available 4TB (~32 trillion bits) SSD weighs 32 grams; a data density of 1 trillion bits/g, about 19 times higher than a comparable hard drive, or about 5.3 trillion times the data density of the Rosetta Stone!
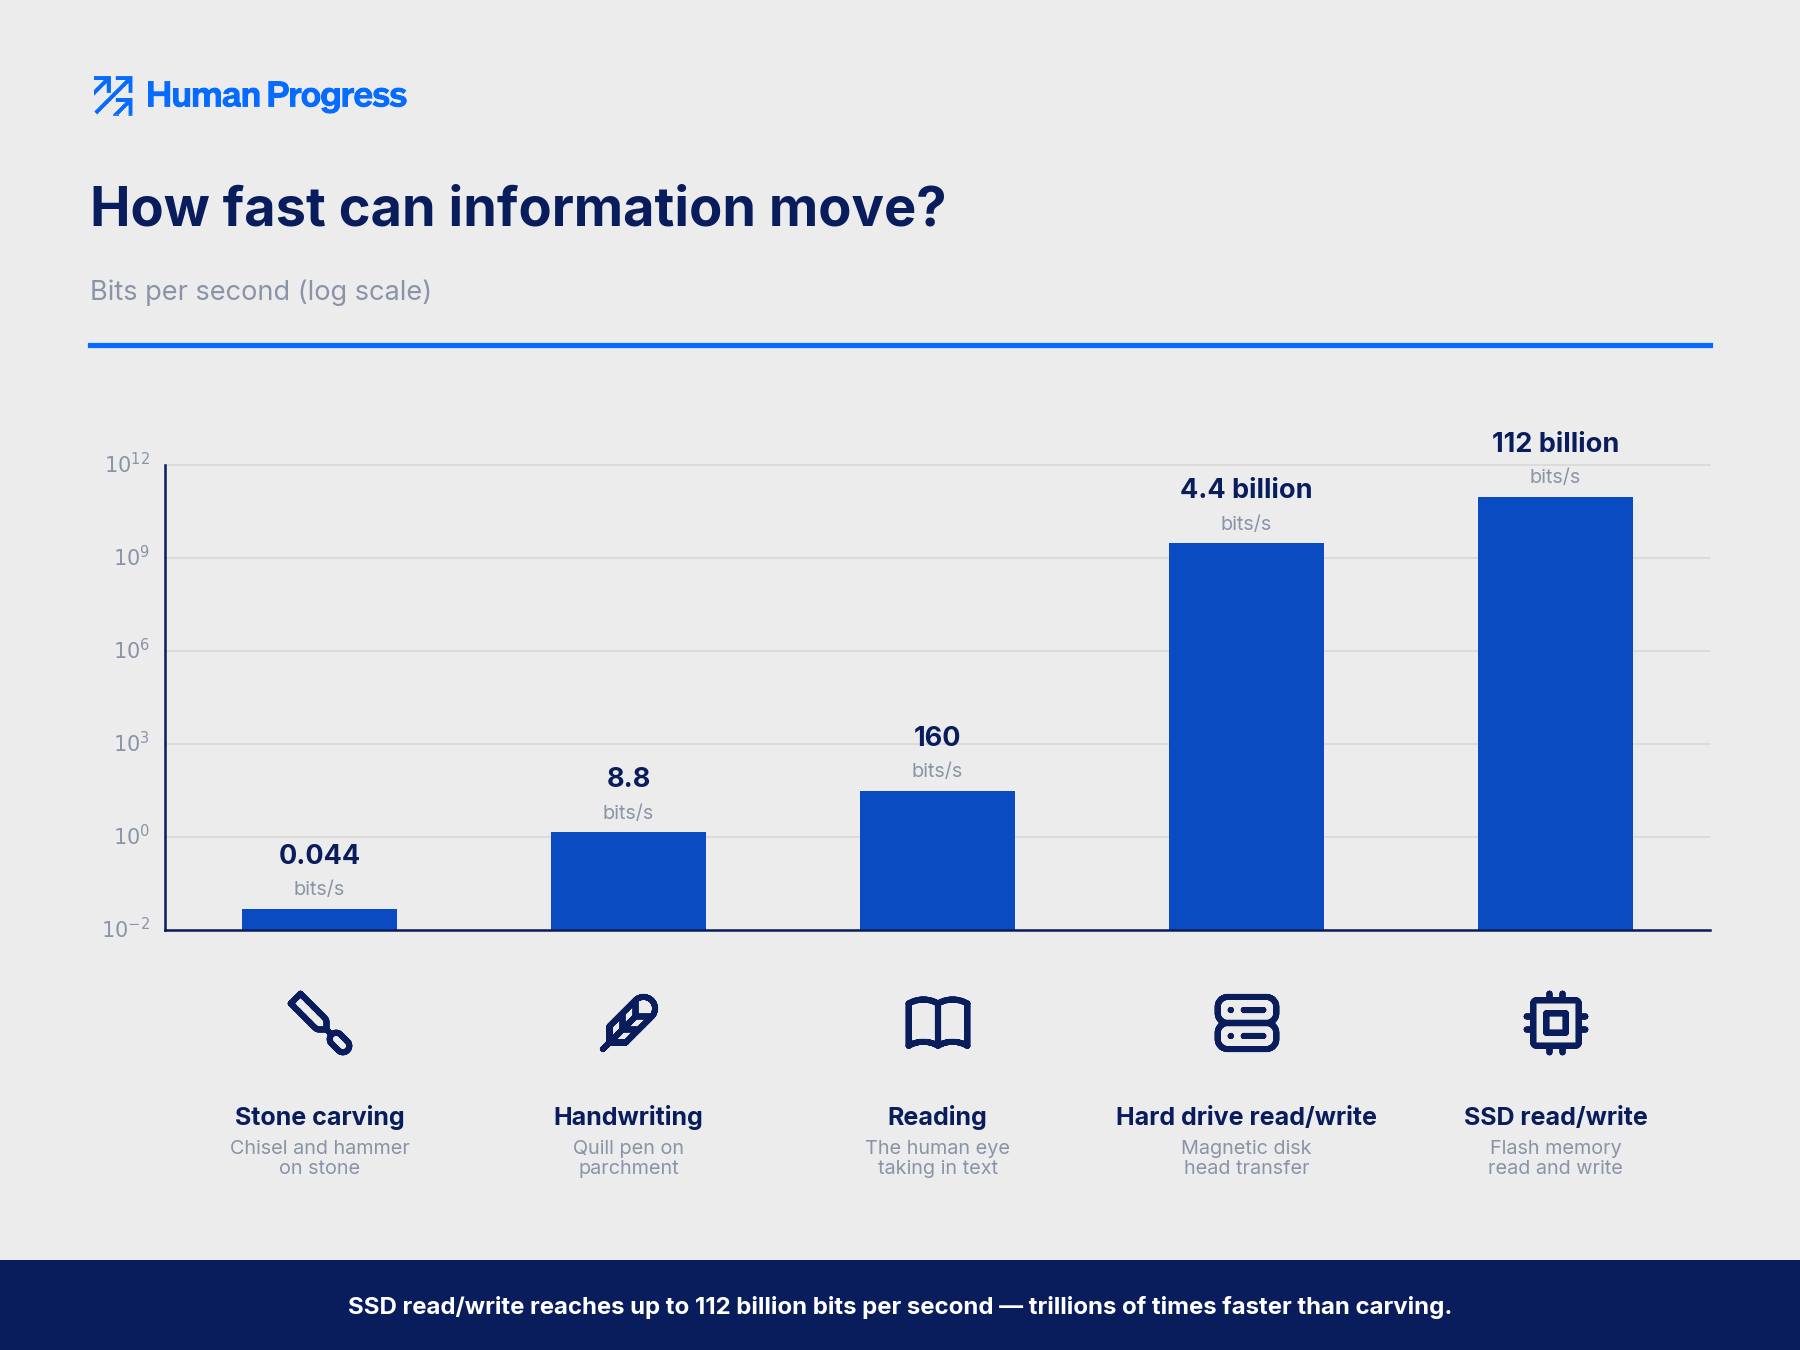
Commensurate with improvements in data density came higher read/write speeds, or “throughput.” People read about 4 words a second and with an average word length of around 5 characters; that’s about 160 bits per second. A professional stone carver might be able to write up to 20 letters an hour, or about 0.044 bits per second. Paper and paper-like media dramatically increased writing speed. A human writes about 1.1 characters per second, or roughly 8.8 bits per second – 200 times faster than carving into stone, though still slower than reading. Printing machines, of course, could print text far faster than any human could write by hand.
But none of this compares to magnetic storage, such as modern hard drives, where read/write speeds (which are similar) are currently about 4.4 billion bits per second. SSDs are faster still, reaching read/write speeds up to 112 billion bits per second. That’s about 700 million times faster than reading, and nearly 13 billion times faster than writing by hand, roughly 2.5 trillion times faster than carving into stone!
In roughly five thousand years, we’ve pushed the density of our storage media up by a factor of trillions, and the leaps keep coming faster. It took five millennia to get from stone to the printed page, representing a 180,000-fold gain in data density. In the seventy years since the invention of the hard drive, and with SSDs, humanity has multiplied that density by another 29 million times. For perspective, the text of the King James Bible carved in stone would weigh around 185 tons, nearly as much as a Boeing 747 (without fuel). On an SSD, it weighs less than a grain of sand.
“We’re opening a research preview of the Model Hardware Standard (MHS), a shared specification for AI agents to safely operate physical devices, to a first group of scientific research labs and advanced manufacturers. MHS enables AI agents to operate multiple lab and manufacturing instruments, such as microscopes, liquid handlers, and robotic arms, in parallel, and perform intricate tasks ranging from routine drug discovery experiments to laser calibration on a quantum computer….
It typically takes a lab or manufacturing facility weeks, if not months, to set up and integrate their hardware. Most devices don’t communicate with each other, instead requiring specialists to build bespoke integrations. MHS reduces this integration work to hours or minutes. And by incorporating AI into these tools, MHS also helps researchers and engineers more readily orchestrate autonomous, round-the-clock experiments and workflows, with agents able to reason through each step in an experiment, update parameters in real time, and, in some cases, recover from hardware errors without intervention.”
Public Cyber Vulnerability Discoveries Have Accelerated
“LLMs have shown the ability to make novel discoveries across many domains. How much has this affected the aggregate discovery rate? In the figures below we plot all the data sources we can find, and make some very loose observations:
Discovery of cyber vulnerabilities has accelerated sharply.
Discovery of math results has accelerated somewhat. However this is harder to objectively measure.
Discovery of optimizations has not shown a dramatic acceleration.
These conclusions are based only on public discoveries. It is quite plausible that AI labs are making discoveries internally that they are not disclosing.”
“More than 600,000 artworks and other cultural objects, mostly owned by Jews, were stolen by the Nazis leading up to and during World War II…
But reclaiming these artifacts is often a long and fraught process.
'There's no central repository, no database that's telling you where that art is,' said Joel Greenberg, founder of Art Ashes, a nonprofit that helps families track down and recover art looted by the Nazis…
A team at Santa Clara University in Silicon Valley is aspiring to do just that, with a new AI chatbot that could help streamline the complicated process of getting these works back to their owners…
Right now, the tool is only scraping records from one database — that of the Jeu de Paume museum in Paris. The Nazis warehoused tens of thousands of looted artworks at the museum during World War II and kept elaborate records — records that are now available for anyone to search online in a database alongside archives from several other institutions around the world, including the German Bundesarchiv, the French Archives of the Ministry of Europe and Foreign Affairs, and the U.S. National Archives.
But Santoro said his team's AI tool is more intuitive than the Jeu de Paume's database because it doesn't require users to deal with drop-down menus and input keywords into boxes.
'It enables ordinary language queries to be made of art databases,' he said.
By 'ordinary language,' Santoro means users can type a question using everyday words into the chatbot's interface. For example, entering the sentence, 'What artworks belong to Hugo Simon?' brings up a list of more than 70 belonging to the late Jewish banker and art collector, including stolen works by Picasso and Canaletto.”